


Technical SEO Checklist (2026): A Practical Guide for Business Websites
A practical technical SEO checklist: crawling, indexing, sitemaps, redirects, Core Web Vitals, structured data, hreflang and AI search, with Google sources.
The short answer
- 01
Start with indexing. Open the Page indexing report in Google Search Console and confirm your important pages are indexed. Most technical SEO problems on small business sites show up there first, as pages blocked, set to noindex, redirected or treated as duplicates.
- 02
Protect your URLs during a redesign. Map every old address to its new page with a single permanent 301 redirect and keep the redirects for at least a year, as Google's site move guide suggests. Missing redirects are one of the most common reasons we see a new website lose its rankings.
- 03
Check speed and AI access on real data. Core Web Vitals pass when 75% of real visits have LCP of 2.5 seconds or less, INP of 200 milliseconds or less and CLS of 0.1 or less. For AI search, make sure Googlebot and OAI-SearchBot can reach your pages; Google says AI Overviews need no special files or schema.
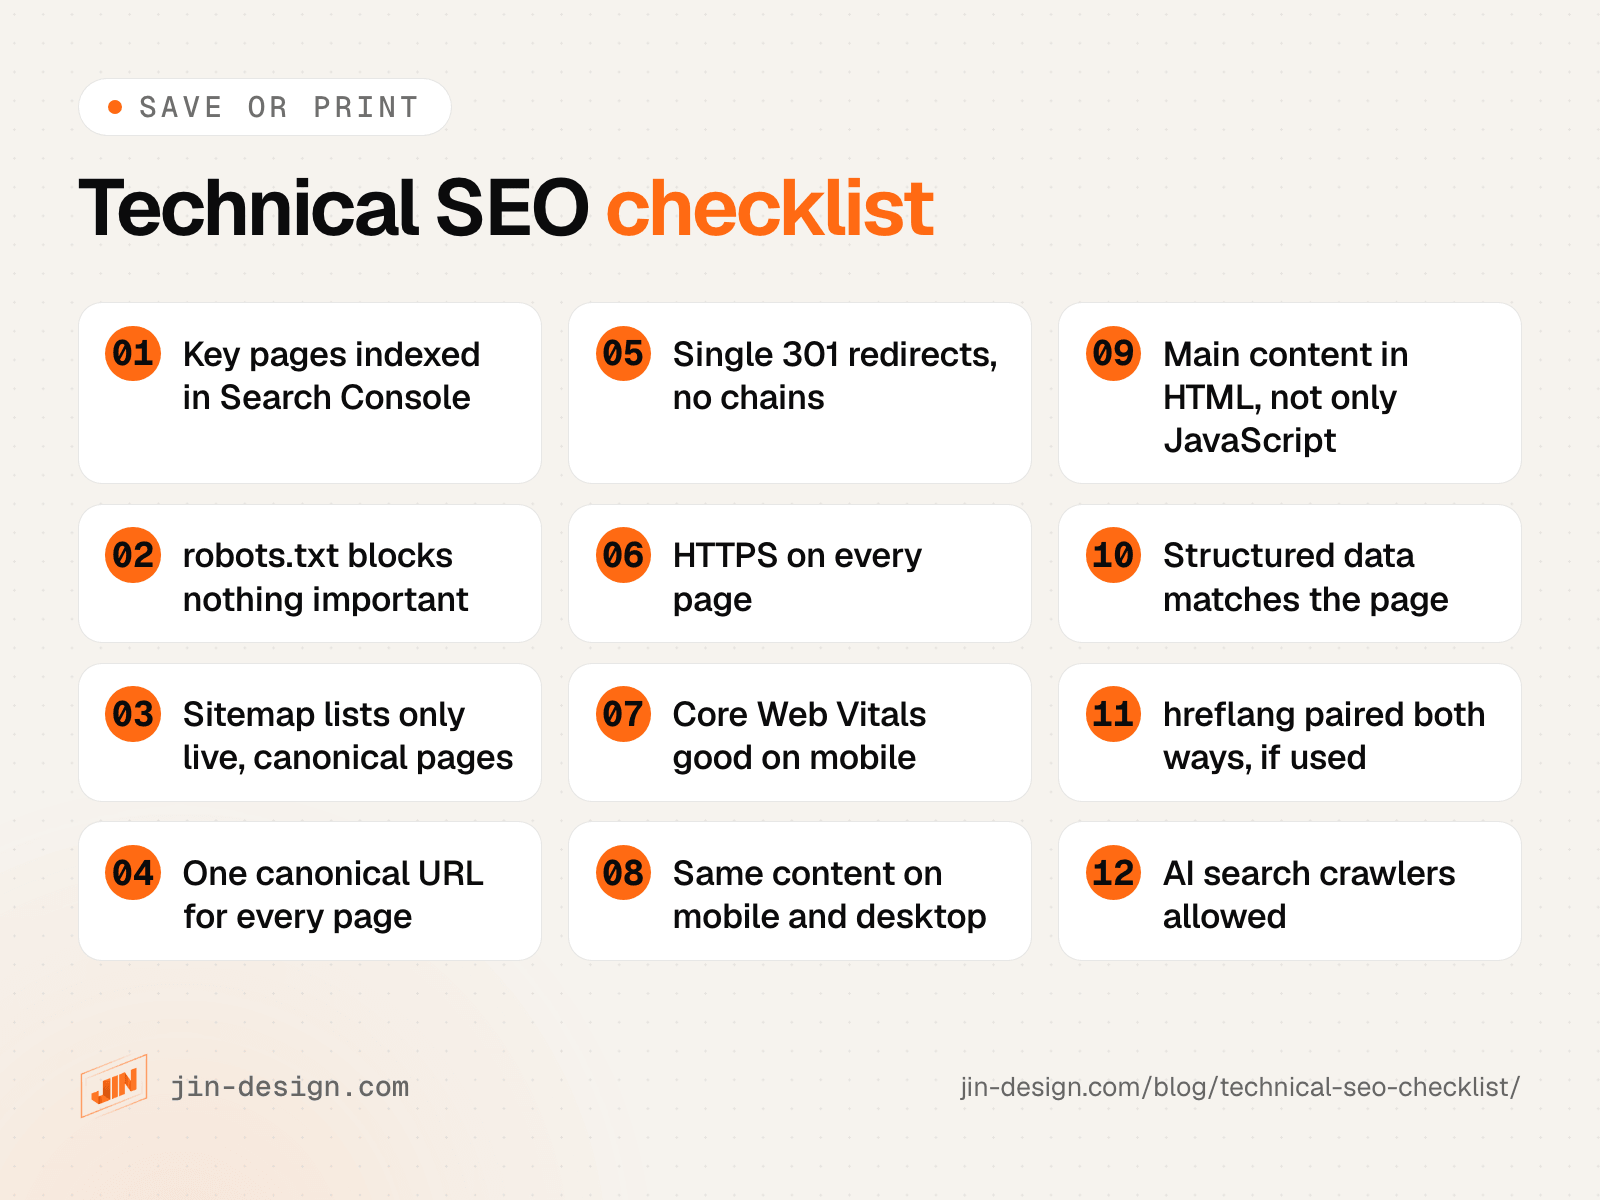
Technical SEO is the work that makes sure search engines can find, crawl, render and index your website, and that its pages load well on phones. This checklist covers the checks that matter for a business website in 2026: indexing in Search Console, robots.txt, sitemaps, canonical tags, redirects during a redesign, Core Web Vitals, mobile, HTTPS, JavaScript, structured data, hreflang for Singapore and Malaysia, and access for AI search crawlers.
Every item is based on Google’s own documentation, linked in each section, and on what we check in our SEO services and website audits. Start at the top: the first few checks catch most of the problems we see on small business sites in Singapore.
What is technical SEO, and what does a technical SEO checklist cover?
Technical SEO is the part of SEO that deals with the website itself rather than the words on it. Content and links decide whether a page deserves to rank; technical SEO decides whether Google can reach the page, understand which version is the real one and show it to searchers on a phone.
| Area | What the check confirms | Where to check it |
|---|---|---|
| Crawling | Search engines can reach every page you want found | robots.txt, internal links, Search Console Crawl stats |
| Indexing | Important pages are in Google’s index, once each | Search Console Page indexing report, URL Inspection |
| Site structure | Old URLs redirect cleanly and links point to final pages | Redirect and sitemap checks, a site crawl |
| Page experience | Pages load quickly, respond fast and work on phones | Core Web Vitals report, PageSpeed Insights |
| Understanding | Structured data and language tags describe the page correctly | Rich Results Test, hreflang checks |
| AI search | Search and AI assistant crawlers can read your pages | robots.txt, CDN bot settings, server logs |
Technical SEO does not replace good content. It removes the obstacles that stop good content from being found, which is why we fix it first in every SEO plan. For the on-page side (titles, headings, internal links), see our guide to on-page SEO for your website.
How do you check that Google can crawl and index your website?
Open Google Search Console, go to Indexing, then Pages, and look at why pages are not indexed. This report is the single most useful technical SEO check, because it shows Google’s own view of your site rather than a tool’s guess.
Google’s help page for the Page indexing report is clear that you should not expect every URL to be indexed. What matters is that the canonical version of each important page is. These are the reasons you will see most often and what to do about each:
| Reason in Search Console | What it usually means | What to do |
|---|---|---|
| Excluded by “noindex” tag | The page asks not to be indexed | Fine for thank-you and admin pages; remove the tag from any page that should rank |
| Blocked by robots.txt | Your robots.txt stops Google crawling it | Unblock it if the page matters; robots.txt does not remove pages from Google |
| Page with redirect | The URL redirects elsewhere | Normal after a redesign; make sure internal links and the sitemap use the final URL |
| Not found (404) | The page no longer exists | Redirect it if it had visits or links, otherwise leave it |
| Soft 404 | The page says “not found” but returns a 200 status | Return a real 404, or put real content back |
| Duplicate without user-selected canonical | Google sees duplicates and picked one itself | Add a canonical tag pointing to the version you want |
| Alternate page with proper canonical tag | The page points to its canonical correctly | Nothing to do |
| Crawled, currently not indexed | Google read it and chose not to index it yet | Improve the content or merge it with a stronger page; resubmitting rarely helps |
| Discovered, currently not indexed | Google knows the URL but has not crawled it | Link to it from important pages and keep it in the sitemap |
For a single page, paste its address into the URL Inspection tool at the top of Search Console. It shows whether the page is indexed, which canonical Google chose, when it was last crawled and how Googlebot rendered it.
A common example: during a redesign, a page is accidentally left set to noindex, and its impressions fade away over the following weeks. A monthly look at this report catches problems like that within weeks instead of months.
Is your robots.txt file blocking anything important?
Your robots.txt file sits at the root of your domain (for example https://www.example.com/robots.txt) and tells crawlers which paths they may visit. Google’s robots.txt introduction says it is for managing crawler traffic and “is not a mechanism for keeping a web page out of Google”. A blocked page can still appear in results if other sites link to it, just without a description. To keep a page out of Google, use a noindex tag or a password instead.
Check these points in your robots.txt:
- No important path is disallowed. Staging rules such as
Disallow: /copied to the live site are a classic launch mistake. - CSS and JavaScript are not blocked. Google renders pages like a browser, so it needs the files that build the layout.
- Each named crawler group repeats your rules. Google’s robots.txt specification says a crawler follows only the most specific group that matches it, and other groups are ignored. If you add a
User-agent: GPTBotgroup withAllow: /, GPTBot no longer reads theDisallowlines in yourUser-agent: *group. Our own robots.txt repeats the same Disallow lines in every group for this reason. - The file returns properly. Google treats a 4xx response (other than 429) as if there were no robots.txt. A 5xx error is worse: Google stops crawling the site for a time while it retries.
- The file includes your sitemap. Add a
Sitemap:line with the full address of your XML sitemap.
Does your XML sitemap list only live, canonical pages?
An XML sitemap tells search engines which pages you want indexed. Google’s guide to building a sitemap sets a limit of 50,000 URLs or 50 MB uncompressed per file, with a sitemap index file for larger sites. A sitemap is a weak signal on its own, so it works best when it agrees with your canonical tags and internal links.
- List only pages that return 200 and are the canonical version. Redirects, 404s, noindex pages and parameter URLs waste crawling and send mixed signals.
- Keep
lastmodhonest. Google uses it only if it is “consistently and verifiably” accurate. Set it when the content changes meaningfully, not on every page load or footer update. - Skip
priorityandchangefreq. Google says it ignores both. - Submit it in Search Console under Indexing, then Sitemaps, and check the number of discovered pages looks right.
Our free XML sitemap checker loads every URL in your sitemap and flags broken pages, redirects, noindex tags, mismatched canonicals and bad dates, with a fix for each.
Does every page have one canonical URL?
The same page can often be reached at several addresses: with and without www, with tracking parameters, with a trailing slash or without, or through a category path in an online store. A canonical tag tells Google which version you want shown:
<link rel="canonical" href="https://www.example.com/services/aircon-servicing/" />Google’s guide to canonicalization lists redirects and rel="canonical" as strong signals and sitemap inclusion as a weak one, and says they work best together. Google still makes the final choice based on how similar the pages are, so the tag is a strong preference rather than a command.
- Every indexable page has a self-referencing canonical with the full absolute URL, including
https://. - The canonical points to a page that returns 200, not to a redirect, a 404 or a noindex page.
- Internal links and the sitemap use the canonical URL, so all signals agree.
- Do not use robots.txt or noindex to handle duplicates. Google advises against both, and a noindex tag would remove the page from Search entirely.
- Pick one host and redirect the rest.
http://,https://,wwwand non-wwwversions should all end at one address with a single redirect.
How do you keep your rankings when you redesign your website?
Map every old URL to its closest new page and set a single permanent 301 redirect for each before launch. A redesign that changes URLs without redirects is one of the most common ways a small business loses its search traffic overnight: Google’s index and every link from other sites still point to the old addresses, which now return 404.
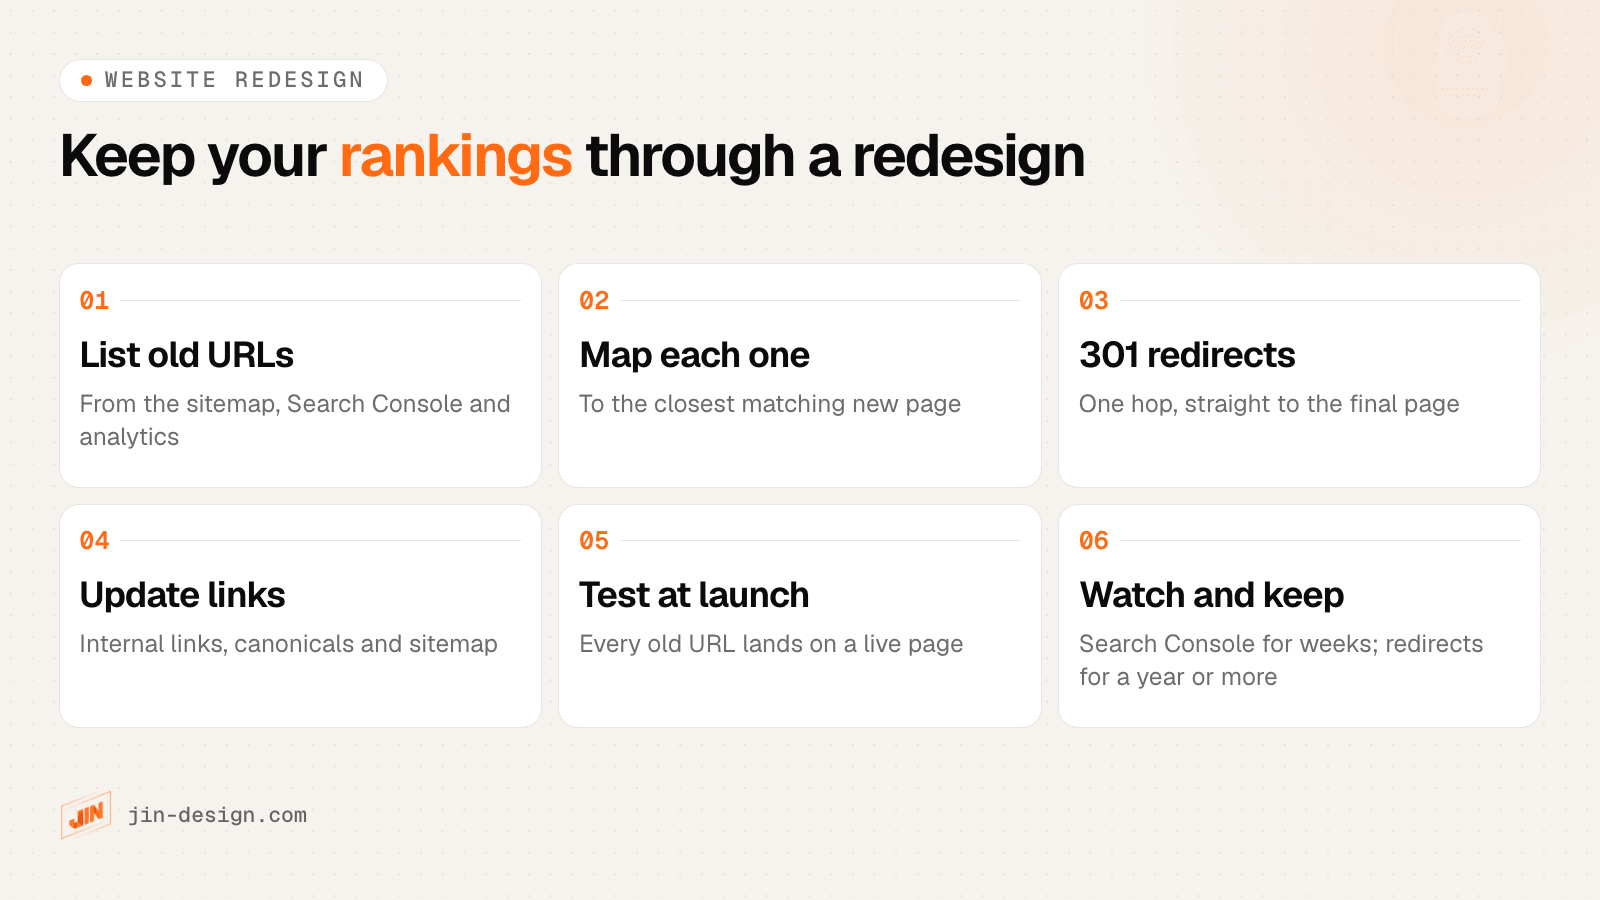
Google’s guide to site moves with URL changes sets out the process. The points that matter most in practice:
- Build the list of old URLs from several sources: the old sitemap, Search Console’s Performance report, analytics landing pages and your CMS. Pages with links from other sites often appear only in Search Console or a backlink tool.
- Redirect each old page to its closest match, not everything to the homepage. Google advises against redirecting many old URLs to one irrelevant page.
- Use permanent redirects (301 or 308) on the server, with one hop. A chain such as old page to
http://tohttps://to the new page slows crawling and loses visitors on slow connections. - Keep the redirects “for as long as possible, generally at least 1 year”, in Google’s words. On our own site we keep them indefinitely, because old links from directories and partner sites keep sending visitors for years.
- Change of domain? Submit a Change of Address in Search Console for the old site. Google says it is not needed for a move from
httptohttpsor betweenwwwand non-www.
When we rebuilt our own site, every article moved from its old WordPress address (/technical-seo-checklist/) to a new path under /blog/. Each old address answers with one 301 straight to its new home, with no chains, and the old category and paginated archive pages redirect to their nearest replacement. Paste a list of old URLs into our free redirect checker after launch to see every hop and spot chains, loops and temporary 302s that should be 301s.
If you are moving to a new site, our website redesign projects include the redirect map and post-launch checks as standard.
What are the Core Web Vitals thresholds in 2026?
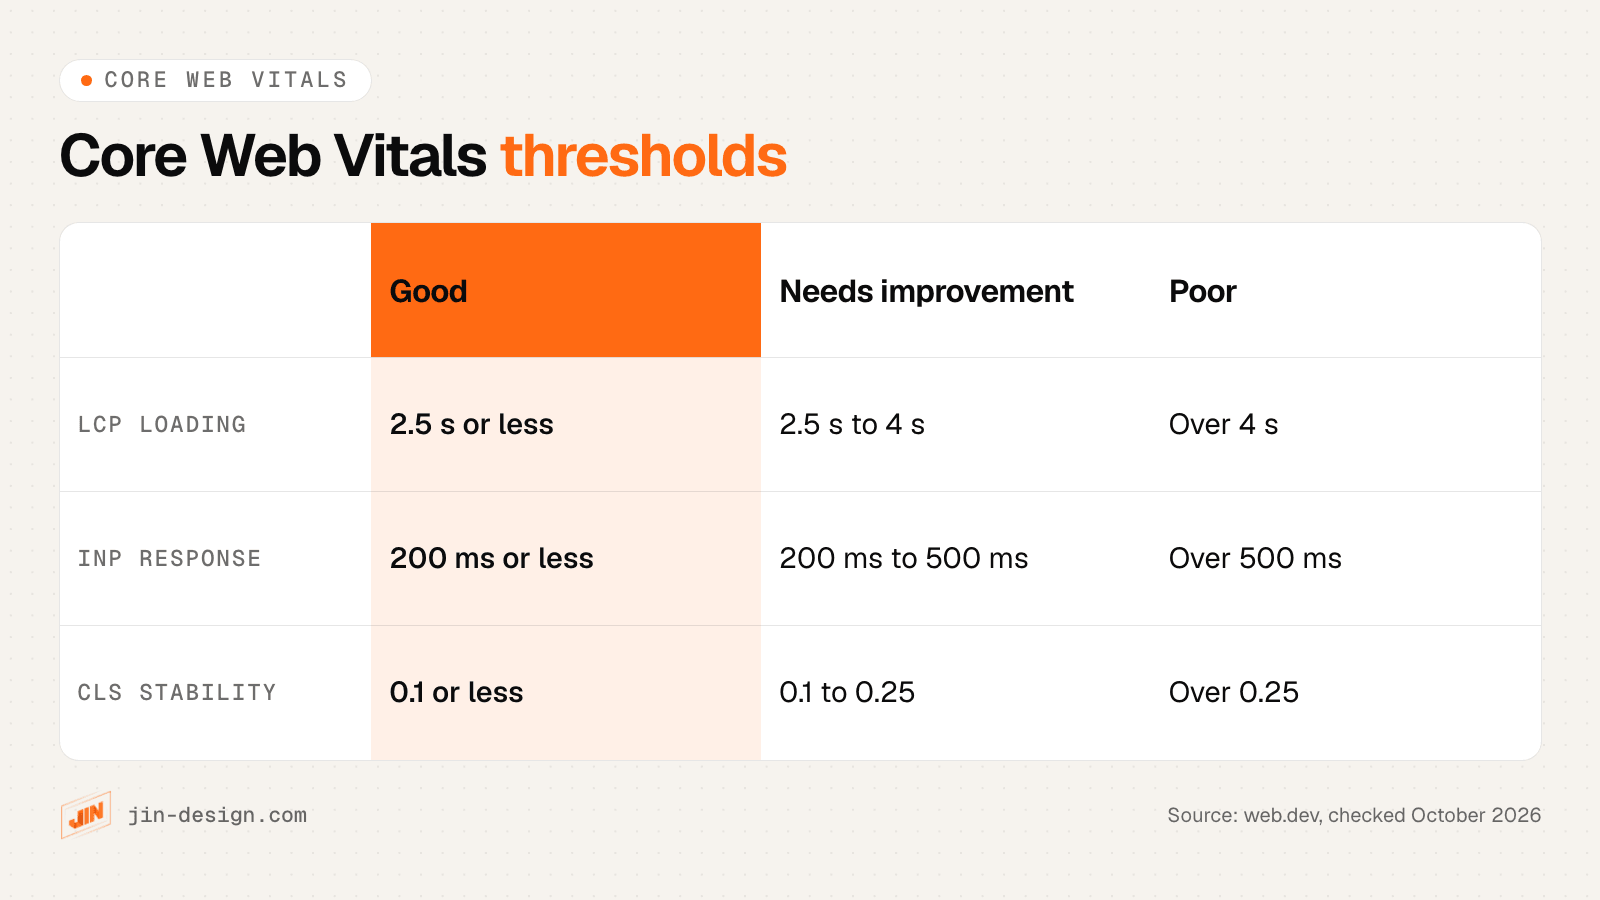
Core Web Vitals are three measures of page experience from real Chrome users. A page passes when at least 75% of visits meet the “good” threshold, measured separately on mobile and desktop. The thresholds, from Google’s web.dev pages on LCP, INP and CLS, are:
| Metric | What it measures | Good | Poor |
|---|---|---|---|
| Largest Contentful Paint (LCP) | How long the main content takes to appear | 2.5 seconds or less | Over 4 seconds |
| Interaction to Next Paint (INP) | How quickly the page responds to taps and clicks | 200 milliseconds or less | Over 500 milliseconds |
| Cumulative Layout Shift (CLS) | How much the layout jumps while loading | 0.1 or less | Over 0.25 |
INP replaced First Input Delay (FID) as a Core Web Vital in March 2024, so any checklist that still lists FID is out of date.
Google’s page on page experience says Core Web Vitals are used by its ranking systems, and also that good scores do not guarantee top rankings. In our experience the bigger cost of a slow site is lost enquiries rather than lost positions, because visitors on a phone leave before the page appears.
Where to look and what usually causes poor scores:
- Search Console’s Core Web Vitals report groups your URLs by status using real-user data, where Google has enough visits. PageSpeed Insights shows the same field data for one page plus a lab test.
- Poor LCP is usually an oversized hero image or slider, a slow server response, or render-blocking scripts and fonts. Serve images in WebP or AVIF at the size they display, and do not lazy-load the main image.
- Poor INP usually comes from heavy JavaScript: page builders, chat widgets, tag managers and third-party scripts competing on the main thread. Remove the scripts you do not need before tuning the rest.
- Poor CLS comes from images and ads without set dimensions, late-loading banners and web fonts that swap in at a different size.
If your site fails on mobile and you are not sure where to start, our website speed optimisation service finds the specific files and scripts behind each poor score.
Is your website ready for mobile-first indexing?
Google uses the mobile version of your pages for indexing and ranking. Its guide to mobile-first indexing recommends responsive design, because the same HTML at the same URL keeps content and metadata identical on every device.
- The mobile page has the same content as desktop. Text, images, links and structured data hidden on mobile may as well not exist for Google. Accordions and tabs are fine.
- Titles, meta descriptions and structured data are the same on both versions.
- Primary content does not wait for a tap or a scroll. Google says not to lazy-load primary content upon user interaction, because Googlebot does not click, swipe or type.
- Tap targets and text are usable on a small screen without zooming. This is a usability point more than a ranking rule, but it decides whether a mobile visitor becomes an enquiry.
Is HTTPS set up correctly on every page?
Every page, image, script and form should load over HTTPS, with every http:// address redirecting to its https:// version in one hop. Search Console’s HTTPS report, listed in Google’s page experience documentation, shows any pages Google found that are not served securely.
- Check for mixed content: an
http://image or script on anhttps://page. Browsers block or warn about it. - Renew certificates automatically and confirm both
wwwand non-wwwhosts are covered. - Use
https://in canonical tags, the sitemap and internal links, so Google does not have to follow a redirect for every page.
HTTPS protects visitors’ data in transit. It does not make a site secure on its own. Plugins, updates and backups matter too: our website maintenance checklist covers them, and our WordPress maintenance plans take care of them for you.
Can search engines read pages built with JavaScript?
Google can, with a delay. Its JavaScript SEO basics describe three phases: crawling, rendering in a headless Chromium browser “once Google’s resources allow”, and indexing. Google still says server-side rendering or pre-rendering “is still a great idea”, because it makes the page faster for visitors and for every crawler.
Some AI crawlers do not run JavaScript at all, so content that only appears after scripts run may be invisible to them. A quick test: open the page, view the page source (not the inspector) and search for a sentence from your main content. If it is not in the source, it depends on JavaScript.
- Main content, headings and links are in the HTML that the server sends.
- Links are real
<a href="...">elements. Google says it can only discover links that are<a>elements with anhrefattribute; buttons that change pages with script are not followed. - Single-page apps return real 404s for missing pages, or add a noindex tag, to avoid soft 404s.
- Titles, canonicals and structured data are in the initial HTML, not added later by script, where you can manage it.
Does your structured data match what visitors see?
Structured data (schema markup) describes your page in a format machines can read: your business name, address and opening hours, an article’s author and date, a product’s price and availability. Google’s structured data guidelines recommend JSON-LD, and they set two rules that catch many sites out:
- Mark up only what visitors can see on the page. FAQ answers, reviews or prices that exist only in the code break the guidelines.
- Valid markup does not guarantee a rich result. Google decides when to show one.
For most Singapore business websites, the useful types are Organization or LocalBusiness on the homepage and contact page (with the same name, address and +65 phone number as your Google Business Profile), Article on blog posts, Product on product pages and BreadcrumbList across the site. Test each page type with Google’s Rich Results Test and watch the Enhancements reports in Search Console.
Our free schema markup generator builds JSON-LD for these types and writes Singapore addresses, phone numbers and opening hours in the right format.
How should Singapore and Malaysia websites use hreflang?
Use hreflang only when you have more than one version of the same page for different languages or countries, such as an English site for Singapore and another for Malaysia, or English and Chinese versions. Google’s guide to localized versions sets the rules:
<link rel="alternate" hreflang="en-SG" href="https://www.example.com/sg/" />
<link rel="alternate" hreflang="en-MY" href="https://www.example.com/my/" />
<link rel="alternate" hreflang="zh-SG" href="https://www.example.com/sg/zh/" />
<link rel="alternate" hreflang="x-default" href="https://www.example.com/" />- The language comes first, then the optional region:
en-SG,en-MY,zh-SG,ms-MY. A country code on its own, such ashreflang="sg", is invalid. - Every version lists every other version, and itself. Google says that if two pages do not both point to each other, the tags are ignored. This return link is the most common hreflang error.
- Add
x-defaultfor visitors whose language or country matches none of your versions, often a country selector or your main site. - Each version has its own self-referencing canonical. Do not point the Malaysia page’s canonical at the Singapore page.
Two Singapore and Malaysia points the big global checklists miss, both from Google’s guide to multi-regional sites:
- Do not redirect visitors by IP address. Google says “most, but not all” of its crawls come from the US and that it may not find every variation if content changes by location. A site that sends Malaysian visitors to
/my/automatically may never have that version crawled. Show a country suggestion banner instead and let people choose. - A
.sgdomain is a strong country signal; server location is not. Google calls ccTLDs “a strong signal” that a site is meant for a country, and says server location is “not a definitive signal”. A Singapore business can rank in Singapore on a site hosted in Malaysia or behind a global CDN, as long as the content and signals say Singapore.
If your site has only one English version for Singapore, you do not need hreflang. Adding it with mistakes does more harm than leaving it out.
Can AI search tools such as ChatGPT and Google AI Overviews read your website?
They can if your robots.txt and your hosting or CDN let their crawlers in, and if your main content is in plain HTML. Google says there are no additional requirements to appear in AI Overviews or AI Mode: a page must be indexed and eligible for a normal search snippet. Its page on AI features and your website also says you do not need new machine-readable files, AI text files or special schema.
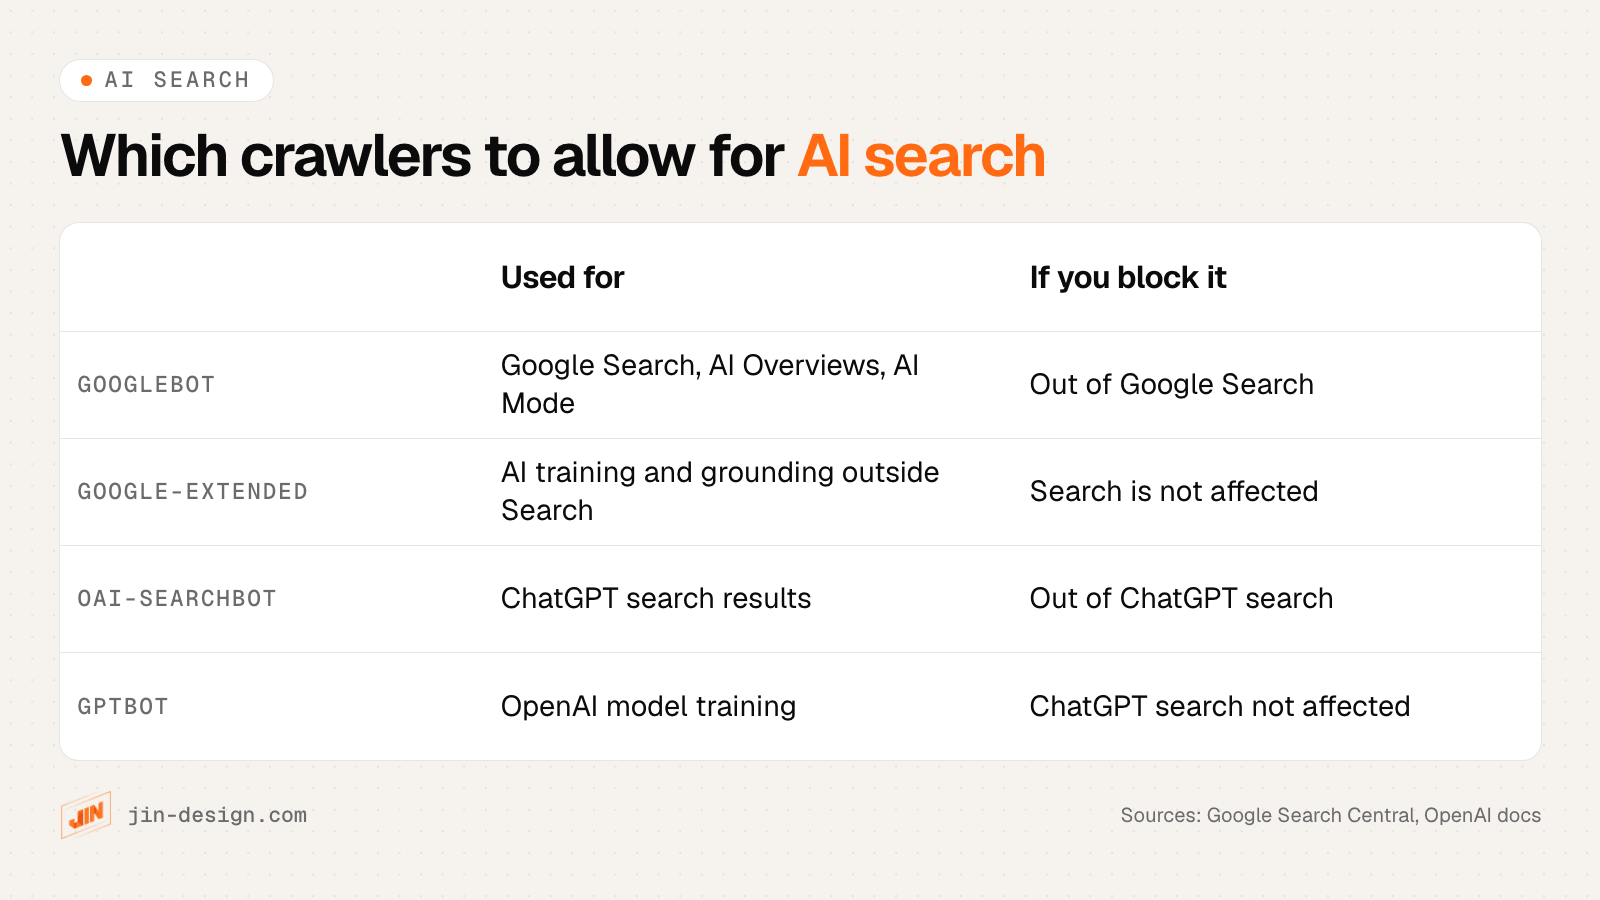
The crawlers you will see most often in your logs:
| Crawler | Used for | If you block it |
|---|---|---|
| Googlebot | Google Search, including AI Overviews and AI Mode | Your pages drop out of Google Search |
| Google-Extended | AI training and grounding in some Google systems outside Search | Google Search is not affected |
| OAI-SearchBot | Finding pages to show in ChatGPT search | Your pages are left out of ChatGPT search results |
| GPTBot | Collecting content that may train OpenAI’s models | ChatGPT search is not affected |
| ChatGPT-User | Visiting a page when a ChatGPT user asks it to | OpenAI says robots.txt rules may not apply, because a user starts the visit |
OpenAI’s crawler documentation says each of its settings is independent, so a business can allow OAI-SearchBot for search visibility and still disallow GPTBot for training. Decide this on purpose instead of leaving it to defaults.
Check these points too:
- Your CDN or security plugin is not blocking AI crawlers you want. Cloudflare, for example, changed its default on 1 July 2025 so that new domains block AI crawlers unless the site owner allows them. Check the AI crawler settings on existing sites too. Google’s own guidance asks site owners to allow crawling in robots.txt and in any CDN or hosting layer.
- Your key facts are in text: what you do, where, for whom and how to contact you, near the top of the relevant page.
- Structured data matches the visible page, as in the section above.
- To limit what appears in Google’s AI features, use
nosnippet,data-nosnippet,max-snippetornoindex, as Google’s AI features page describes. Blocking Google-Extended does not do this.
Our free AI search visibility checker shows which search and AI crawlers can reach a page and whether its content and structured data are easy to read. For an ongoing plan, see our AI search optimisation service. No one can guarantee that an AI assistant will mention or cite a business; these checks remove the technical reasons it cannot.
How often should you run a technical SEO checklist?
Look at Search Console once a month and run the full checklist once a quarter. Run it again before and after any redesign, change of platform, change of domain or major plugin update, because those are the moments sites lose rankings.
| When | What to check |
|---|---|
| Monthly | Page indexing report for new errors, Core Web Vitals report, any security or manual action messages |
| Quarterly | The full checklist above, a crawl of the site for broken links and redirect chains, sitemap health |
| Before a redesign | Export all URLs, top landing pages and pages with links; write the redirect map |
| Launch day | robots.txt and noindex removed from staging settings, every old URL tested, new sitemap submitted |
| Two to six weeks after launch | Page indexing report, Performance report compared with the weeks before launch, 404s from old links |
Results depend on your content, your competitors and how long Google takes to recrawl, so a technical fix rarely shows up in rankings the next day. Fixes to indexing problems on important pages are usually the first to make a visible difference.
Need help with technical SEO for your website?
Our SEO services include technical SEO as part of every monthly plan: we check Search Console, fix crawling, indexing, speed, structured data and redirect issues on the site, and report on the searches that led to enquiries. If you want a one-off review first, a website audit gives you a fix list ranked by business impact, which your own developer or our team can work through.
If you are comparing providers, our guide to SEO agencies in Singapore lists what each offers, or talk to us about your site. To check how your pages will look in Google before you change titles and descriptions, try our free title and meta description checker.
Frequently asked questions
What is a technical SEO checklist?
A technical SEO checklist is a list of checks that confirm search engines can find, crawl, render and index your website, and that its pages load well on phones. It covers robots.txt, XML sitemaps, canonical tags, redirects, HTTPS, Core Web Vitals, mobile content, JavaScript rendering, structured data, hreflang and access for AI search crawlers.
What is the difference between SEO and technical SEO?
SEO is everything that helps a page earn visits from search: the content, the keywords it answers, links from other sites and the technical set-up. Technical SEO is the part about the website itself, making sure search engines can crawl and index the pages and that they load quickly and work on phones. Good content cannot rank if Google cannot index it.
What are the main components of technical SEO?
The main components are crawling (robots.txt and internal links), indexing (noindex, canonical tags and the Page indexing report), site structure and redirects, sitemaps, page experience (Core Web Vitals, mobile and HTTPS), rendering of JavaScript, structured data, international targeting with hreflang, and today, access for AI search crawlers.
How often should you do a technical SEO audit?
Check Search Console every month for new indexing errors and run the full checklist once a quarter. Run it again before and after any redesign, platform change or URL change, because that is when most rankings are lost.
Do Core Web Vitals affect Google rankings?
Yes, Google says Core Web Vitals are used by its ranking systems, but good scores do not guarantee top positions. Relevance and content quality matter more. Treat a pass as one requirement among several and fix poor scores on the pages that bring enquiries first.
Do you need llms.txt or special schema to appear in Google AI Overviews?
No. Google says there are no additional requirements to appear in AI Overviews or AI Mode, and no special schema or AI text files are needed. A page has to be indexed and eligible to show a snippet in normal search, so the usual technical SEO checks are what matter.
What is the 80/20 rule in SEO?
The 80/20 rule is a rule of thumb that a small share of the work brings most of the results. In technical SEO it means fixing the few issues that affect your most valuable pages first, such as a key service page that is not indexed or a redirect lost in a redesign, before polishing minor warnings across the whole site.